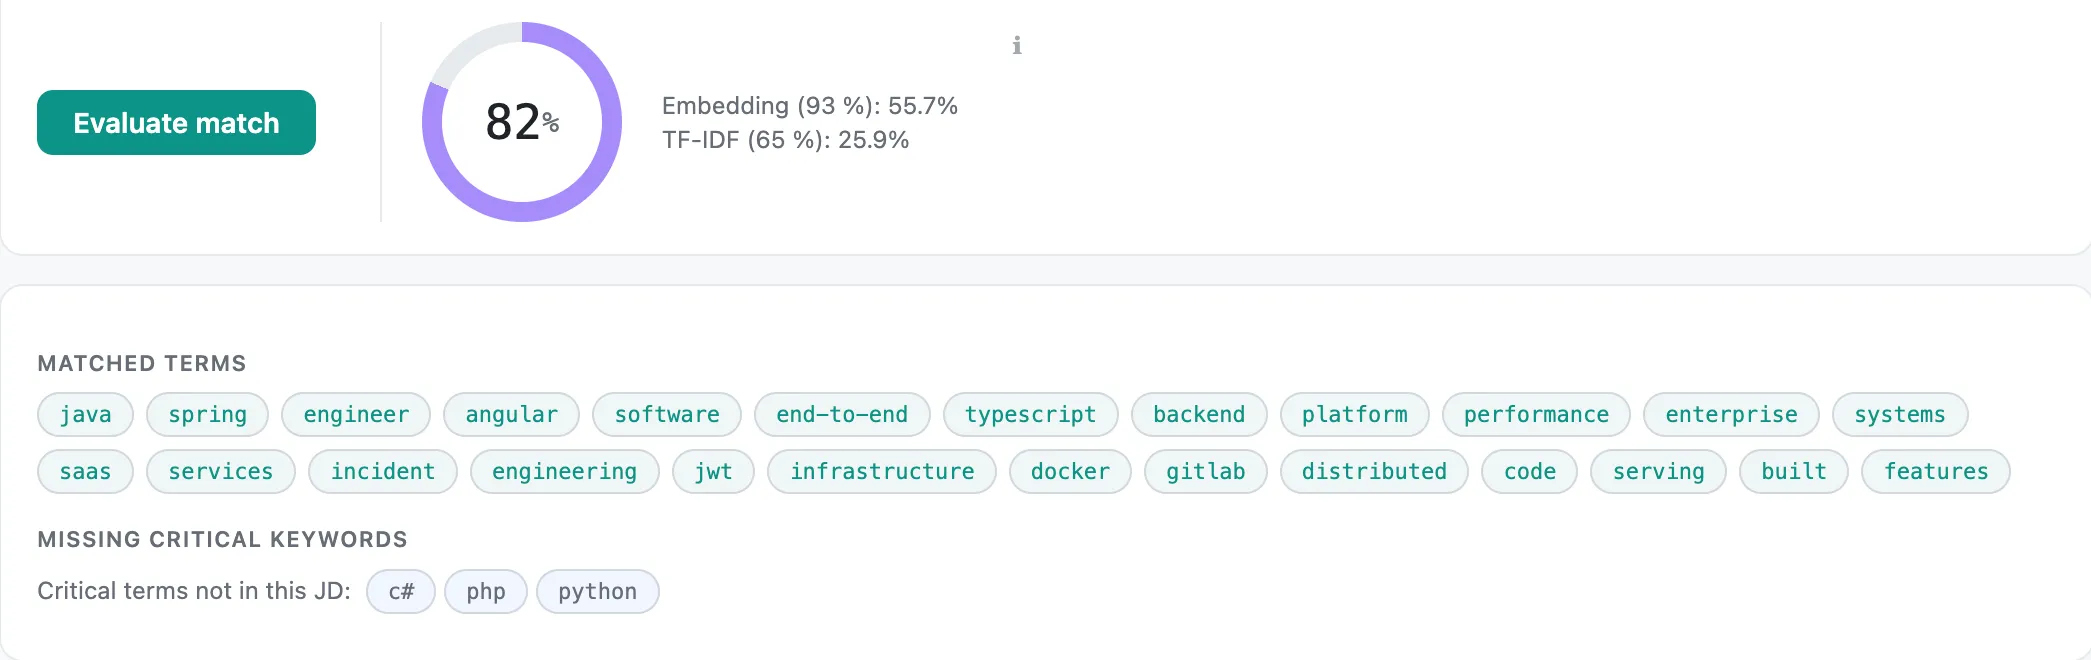
A framework-free library that scores how well a resume matches a job description, combining semantic embedding similarity with keyword TF-IDF. It has no UI and no server of its own — it’s the shared engine that ResuRank and ResuRank MCP both import, so a scoring change only has to be made once.
npm install @resurank/scoring @huggingface/transformersimport { scoreResumeAgainstJob } from '@resurank/scoring';import { createTransformersEmbedder } from '@resurank/scoring/node-embedder';
const embedder = createTransformersEmbedder();
const result = await scoreResumeAgainstJob( resumeText, { title: 'Senior Backend Engineer', description: jdText }, embedder,);
result.score; // 0–1result.matchedTerms; // top-weight overlapping termsresult.missingTerms; // missing pinned terms, when configuredresult.breakdown; // semantic / keyword / penalty breakdownThe embedding step is pluggable behind a one-method Embedder interface — swap in a Web Worker, a different ONNX model, or a remote embedding API without touching the scoring math itself.
How scoring works
- Text preparation — stopwords stripped, the job title double-weighted, HTML/Markdown/URLs sanitized, both texts capped at 6,000 characters
- Semantic score — cosine similarity between resume and JD embeddings from
Xenova/jina-embeddings-v2-small-en, run fully on-device via Transformers.js - TF-IDF score — keyword cosine similarity plus an overlap bonus (up to +20pp) for shared top terms, with optional per-term boosts
- Weighted blend — 60% semantic + 40% TF-IDF under normal conditions
- Divergence adjustment — smoothly shifts weight toward TF-IDF as it approaches zero, so two unrelated documents can’t score high on semantic similarity alone
- Critical missing keywords (optional) — flag must-have terms across Low/Medium/High importance tiers; their absence reduces the score, capped at a 50% reduction
- Preference mismatch penalty (optional) — embed traits you don’t want in a role and penalize JDs that match them
- Language detection — flags job descriptions that are mostly non-ASCII, since cross-lingual embedding similarity is less reliable
Features
- Subpath exports —
@resurank/scoringships pure scoring/types with no model dependencies;/node-embedderand/constantsare separate entry points so browser or worker consumers can skip bundling Node-only Transformers.js code Embedderinterface — a one-method contract (embed(texts: string[]): Promise<number[][]>) that decouples the scoring math from any specific embedding backend- Score tiers — Poor fit / Fair / Good / Great fit at a glance
- Shared by two consumers — the ResuRank desktop app resolves it via an npm workspace symlink; ResuRank MCP pulls it from the npm registry
@resurank/scoring on npm
npm install @resurank/scoring @huggingface/transformers
www.npmjs.com